Data Center Exit on AWS (2026): Wave Design, the 22-Month Program, and Why Big-Bang Cutovers Fail on People Before Tech
Quick summary: A composite mid-market manufacturer exited a colo of 150 workloads and ~400 TB in 21 months across 8 waves, with 47 minutes of unplanned cutover downtime (industry median per Gartner: ~4 hours per major cutover). The single-wave alternative bid came in at ~$4.8M; the wave-based program ran ~$2.1M. The post covers how the wave plan, dependency cutoff, and rollback layer fit together against a hard landlord deadline.
Key Takeaways
- The single-wave alternative bid came in at ~$4.8M; the wave-based program ran ~$2.1M
- AWS lifecycle notice (June 30, 2026): AWS Directory Service Simple AD is in maintenance for new customers after July 30, 2026
- By June 2026, AWS has shipped the second-generation AWS Transform MGN console refresh and tightened MAP funding gates, and lease and colo contracts signed in the 2021 to 2023 wave are now expiring
- These programs look nothing like the 2018 "5-year lift-and-shift" projects; they are wave-based, deadline-driven programs of work
- It is not a migration strategy explainer, and it is not the cloud-exit reversibility post (which is the opposite problem: making AWS workloads portable)
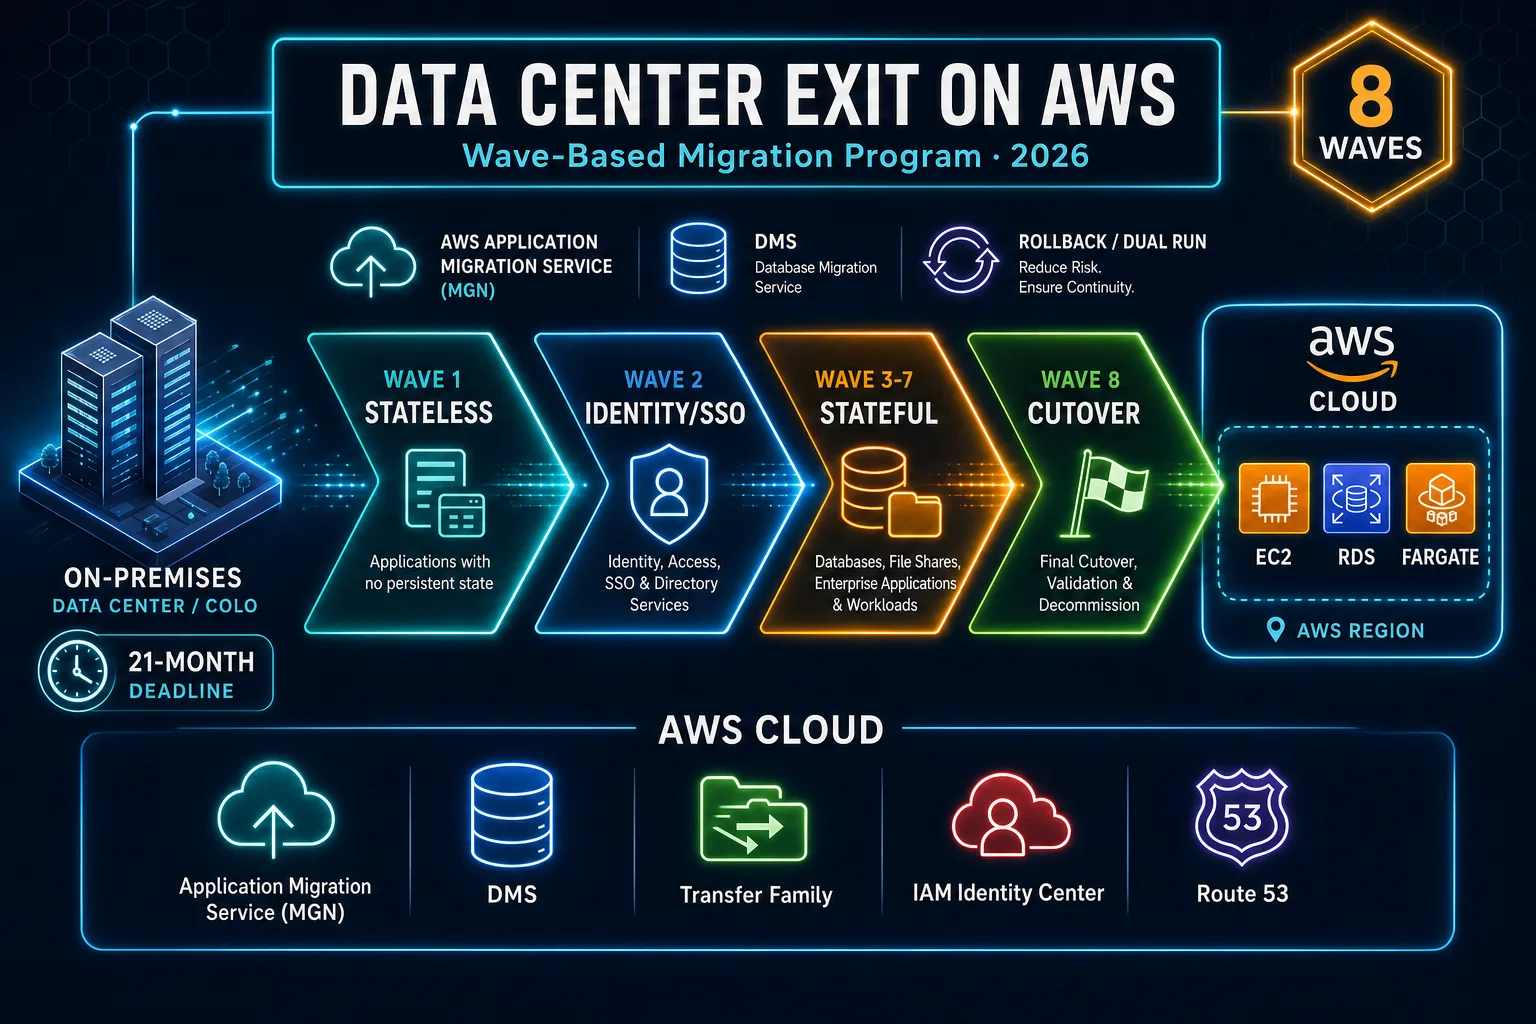
Table of Contents
By June 2026, AWS has shipped the second-generation AWS Transform MGN console refresh and tightened MAP funding gates, and lease and colo contracts signed in the 2021 to 2023 wave are now expiring. We are mid-cycle on a wave of large data centre exits. These programs look nothing like the 2018 “5-year lift-and-shift” projects; they are wave-based, deadline-driven programs of work. This is for CIO offices, program directors, and platform leads running one of those exits. It is not a migration strategy explainer, and it is not the cloud-exit reversibility post (which is the opposite problem: making AWS workloads portable). This is the program-management view of moving 100+ workloads off on-prem onto AWS before the landlord clock runs out.
Design the program backwards from the DC-exit clock
A data centre exit programme has exactly one hard constraint: the landlord’s notice-period clock. Everything else (cloud architecture preferences, vendor timelines, internal politics) bends to that date. Design the programme by working backwards:
- Notice + decommission window at the end. 30 to 90 days for physical decommission, certified destruction, and lease-exit paperwork. Read the lease: many require months of written notice before the end date.
- Steady-state proving window before that. 30 days of all workloads green on AWS, no source-side running, before you trigger decom.
- 8 to 10 waves before that, sized 8 to 15 workloads each, with 2 to 4 weeks between waves for retrospective + next-wave readiness.
- Pre-Wave 1 foundation phase before that: landing zone, network baseline, identity, observability, FinOps tagging, runbook templates, and the risk register.
If the math doesn’t fit, the programme is either over-scoped or under-resourced. Wave-based exits typically run 18 to 30 months; below 12 months you are running an incident response, not a programme, and the playbook is different.
Wave design: 8 to 15 workloads, one dependency cutoff, one rollback layer
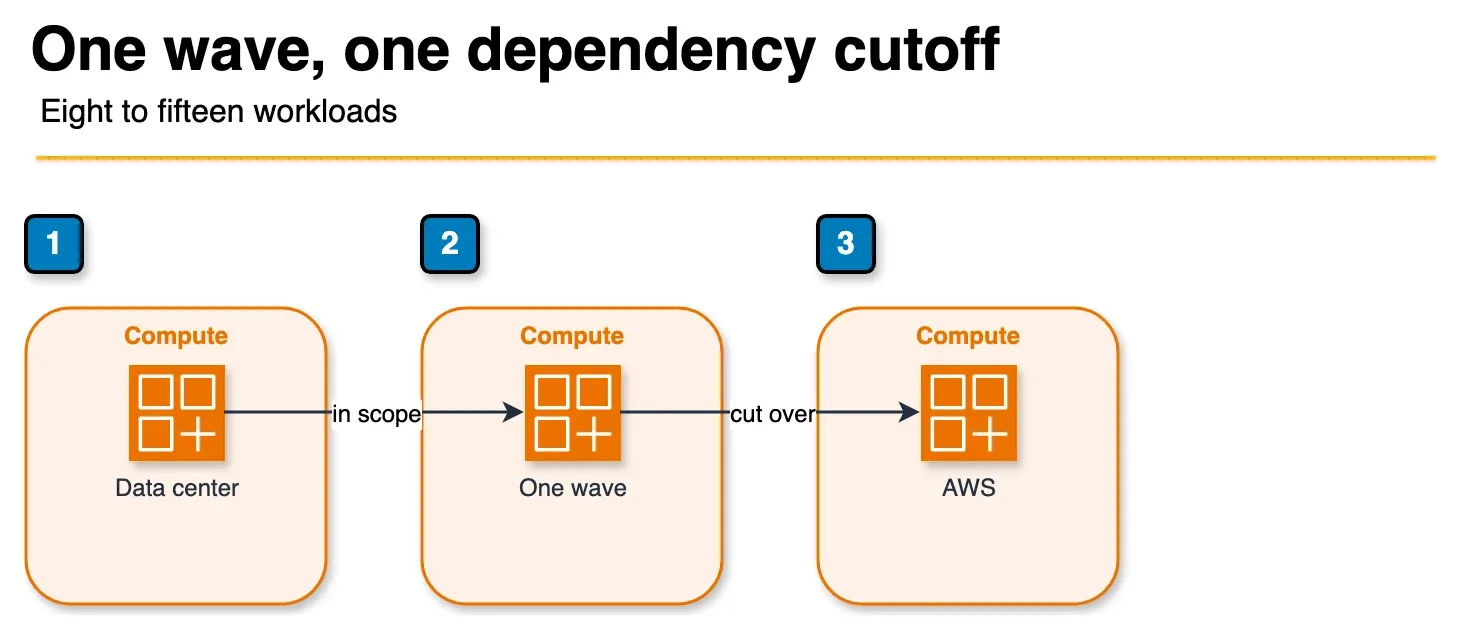
Figure: wave design in the article. A wave holds 8 to 15 workloads and does not depend on work that is still on premises outside that wave. Identity usually moves before customer-facing tiers. The stateful core moves last. Open the draw.io source.
Every wave answers three questions: what moves, how it moves, how it un-moves. The wave plan template captures these as columns; the structure that matters:
| Wave design constraint | What to set | Why |
|---|---|---|
| Size | 8–15 workloads | Below 8, programme overhead dominates; above 15, dependency analysis becomes intractable and on-call burns out |
| Theme | One narrative (“low-risk lift-and-shift”, “file share + identity prep”, “stateful core”) | Reduces context-switching for the cutover team; lets you reuse the runbook template across waves |
| Dependency cutoff | No wave depends on un-migrated work outside its scope | If Wave 3 needs Wave 5’s SSO, Wave 3 either waits or owns a minimal SSO of its own |
| Rollback layer | One named per wave (DNS swap, blue/green ALB, on-prem standby, CDC replication) | Rollback is not a single button; it’s a documented layer with a trigger condition |
| Decom date | 30/60/90/120 days after cutover by criticality | Critical waves keep source warm for 90+ days; lift-and-shift can decom at T+30 |
The opinionated take: size waves to similar criticality. Mixing a low-risk wiki cutover with a high-stakes ERP cutover in the same wave produces a runbook that either over-protects the wiki or under-protects the ERP. Keep them in separate waves with separate runbooks. The wave template above shows this: Waves 1, 6, and 8 are low-risk; Waves 4, 5, and 7 are high-stakes.
The four windows you must define before Wave 1
Programme planning fails most often at window definition. The four windows below are different things, and conflating them produces miscommunication with stakeholders. Define each one explicitly in the master timeline.
- Discovery window: the time between identifying a workload as in scope and starting its wave preparation. Typically 6 to 12 weeks per workload. The bottleneck is rarely tooling; it is the workload owner’s availability for design conversations.
- Dual-run window: the period during which the workload is operational on both source (on-prem) and target (AWS). Sized by replication tooling capacity and the lag SLA: typically 2 to 6 weeks for replatform waves, longer for stateful databases. This is also when most of your data-egress cost lands, so budget for it.
- Cutover window: the actual maintenance window during which writes are paused on source, replication catches up, and traffic redirects to target. 2 to 8 hours for most waves; up to a long weekend for stateful cores like ERP databases.
- Decommission window: the time between successful cutover and physical decom of source. This is your rollback runway. Setting it too short (e.g. < 30 days for a critical workload) trades cost for risk in the wrong direction.
The mistake we have seen: programmes that conflate “cutover window” with “go-live decision” and decommission the source the day after the cutover. The first incident in the post-cutover steady-state then has no rollback, and the programme has to invent one in real time.
What to move first and what to move last
A wave ordering exists in every programme that is empirically defensible, not just opinion. The data points come from the migration-readiness assessment (readiness checklist), the dependency-flow analysis, and the team’s first-hand experience of which workloads have the fewest unknowns.
Move first:
- Workloads with low criticality and few dependencies. Wave 1 builds the cutover muscle; it is not the value delivery wave.
- Identity and SSO: Wave 2 typically. Every customer-facing wave from Wave 3 onwards depends on it.
- Internal-only tools with no customer impact. They prove the network and observability stack without putting customer trust at stake.
Move in the middle:
- Customer-facing web tier: proves the cutover model to customers and unlocks revenue-tier confidence.
- Reporting and analytics: relatively isolated, but stateful, so they exercise the data-migration pattern before the core stateful waves.
- Integration / API tier: depends on web and identity; needs careful trading-partner comms.
Move last:
- Stateful core: ERP, primary database, MES. These have the longest dual-run, the most complex rollback, and the highest stakes.
- Decommission + monitoring stack: Wave 8 in our template. You need the source-side monitoring until the very end; the new AWS-side monitoring takes over only after all other waves are green.
Rollback as a documented layer
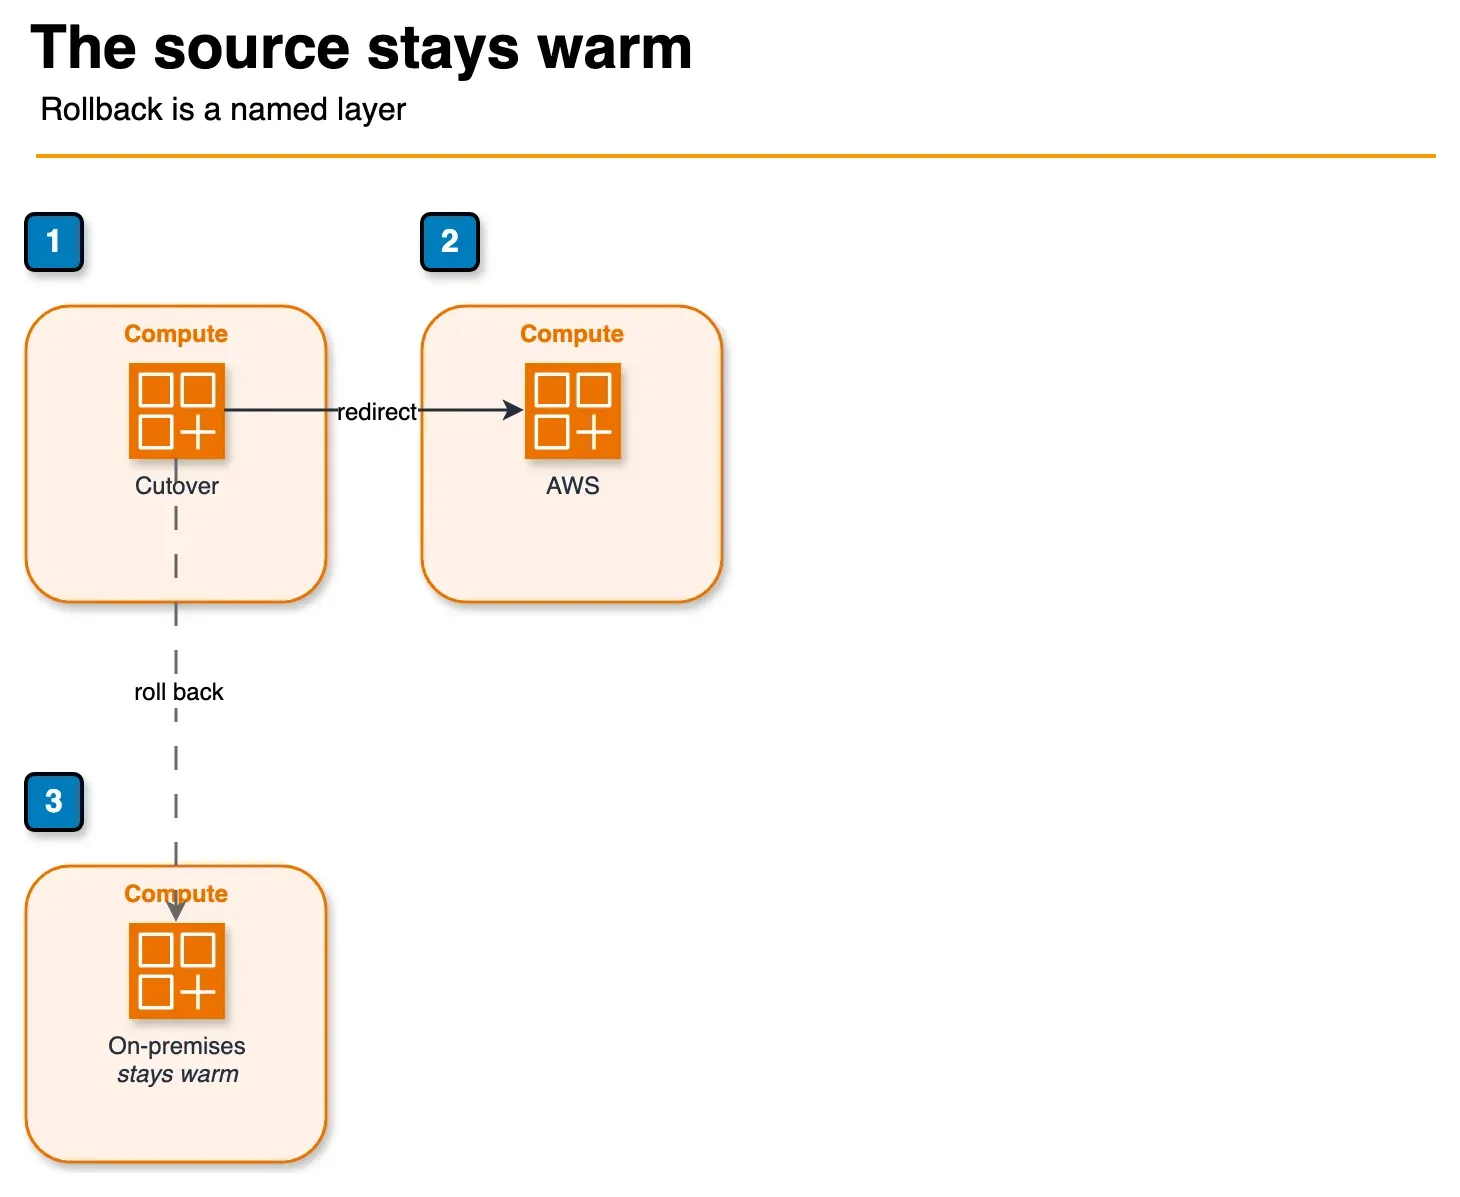
Figure: rollback in the article. Traffic moves to AWS, and the source stays able to take it back. DNS, a blue/green load balancer, or replication is the mechanism for that wave. Measure lag on both sides before the go/no-go. No host names are shown. Open the draw.io source.
The single most common failure of mid-programme cutovers is the absence of a documented rollback. “If it goes wrong we’ll roll back” is not a plan. A rollback layer is:
- Trigger conditions written in advance: error rate > X% of baseline for ≥ 15 min, p95 latency > Y ms, replication-back-to-source fails, SEV-2 customer incident.
- Steps written for the specific workload, not a generic playbook: which DNS records flip, which application config reverts, what queued writes replay, who approves the call.
- Window: how long the source remains warm and capable of taking traffic post-cutover. 30 days minimum for medium criticality, 60 for high, 90 for critical.
- Decision authority: a named individual (with a named alternate) who can call rollback in the middle of the night without escalation delay.
The cutover runbook skeleton has these phases as explicit gates: T-7, T-1, T-0, T+1, T+7, T+30. Copy the file per wave, fill in the specifics, and test the rollback path in a non-production environment at least once before any high-stakes wave.
What to do this week
- Read the colo lease end-to-end and identify the notice clauses. Build the master timeline backwards from the notice date, not the lease-end date.
- Pull a list of every workload running in the DC. Score each on criticality (low/medium/high/critical) and dependency depth (count of inbound + outbound network flows). This is the input to wave assignment.
- Open the wave plan template and group your workloads into 6 to 10 waves of 8 to 15 workloads each. Identify out-of-scope dependencies and resolve them (move workloads to a different wave, or carve out a minimal sub-system).
- Open the risk register. Add owners and dates to every row. Re-prioritise per your estate.
- Copy the cutover runbook skeleton for Wave 1 and fill in the specifics. Test the rollback path in a non-production environment before scheduling the cutover window.
- Brief executive sponsors with the 21-month timeline and the budget envelope from the wave plan. Get explicit approval for the 90-day decom window on critical waves. That is where lease cost meets rollback risk.
What this post doesn’t cover
- Multi-cloud DC exits: moving workloads to AWS and a second hyperscaler simultaneously. Different programme shape, different vendor management.
- Mainframe re-hosting: a specialist programme of its own (z/OS → AWS Mainframe Modernization or partner-managed); the wave model does not fit cleanly.
- HR / staffing ramp for the programme team: sizing the team, contractor strategy, knowledge transfer.
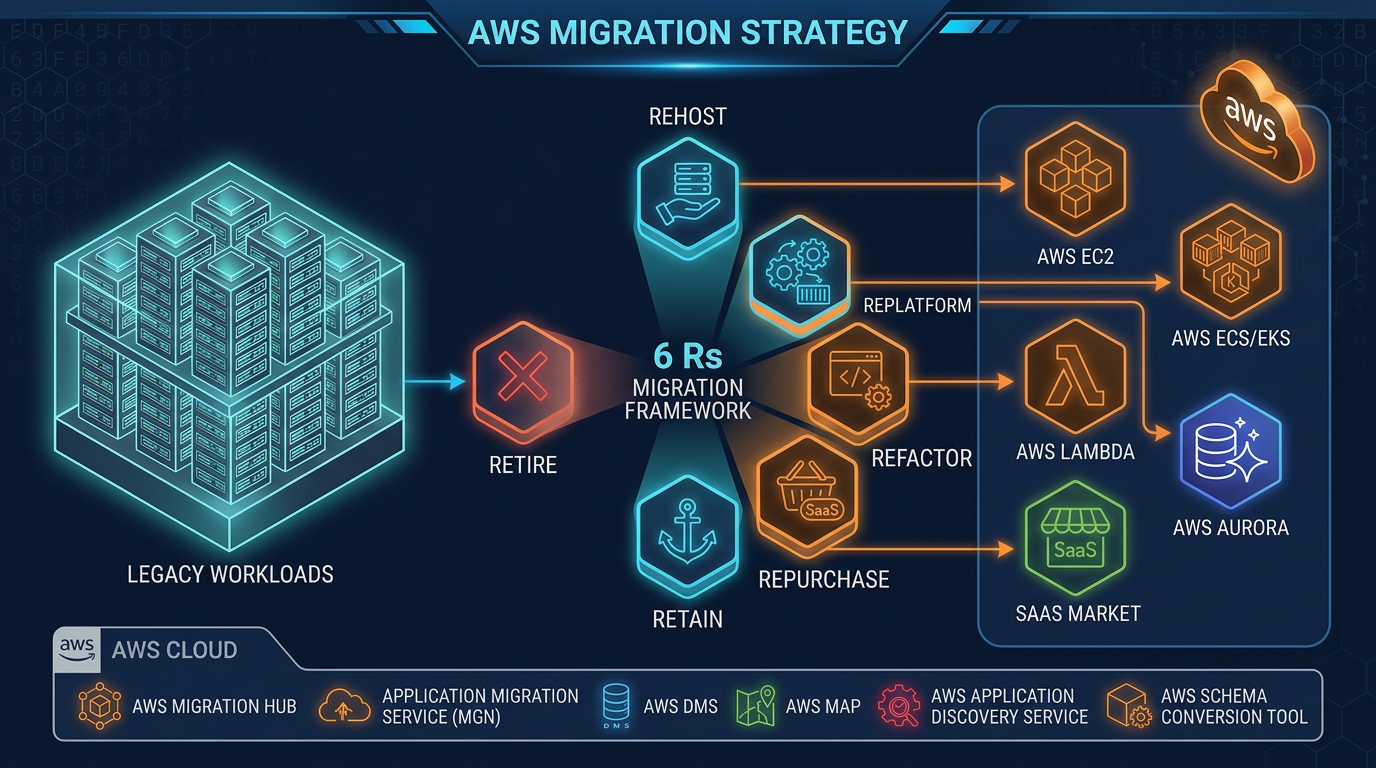
- Detailed migration strategy decisions per workload: the 7Rs framing is covered in the existing strategy post.
- MAP funding mechanics in 2026: eligibility, milestones, and credit application, covered separately.
- Migration cost surprises during dual-run and steady-state, covered in the existing FinOps-for-migration post.
- Cloud exit from AWS: see the cloud exit and reversibility post; reversibility is not the same problem as DC exit.
Related: Cloud migration consulting · Migration readiness checklist · Post-migration optimization & FinOps handoff · Migration without cost surprises · Cloud exit and reversibility
If you only do one thing: Build the master timeline backwards from the notice date in your colo lease, not the lease-end date. Many exits stall on a notice clause discovered in month 14.
Frequently asked questions
How is this different from the cloud-exit reversibility strategy post?
When should we NOT do a wave-based DC exit?
Can we use AWS Transform MGN (formerly AWS Application Migration Service) for the whole estate?
What goes wrong when waves are too large?
Should we move stateless or stateful workloads first?
What if we discover a workload is not cloud-ready mid-program?
AWS Cloud Architect & AI Expert
AWS-certified cloud architect and AI expert with deep expertise in cloud migrations, cost optimization, and generative AI on AWS.