SageMaker Production MLOps on AWS (2026): Inference Components, Capacity Pools, and Promotion Gates
Quick summary: On a fraud-scoring team (~450 RPS peak, ml.g5.2xlarge), inference components plus April 2026 capacity-aware instance pools cut endpoint provisioning failures from 6 retries to 0, and p99 held at 68 ms through a g5→g6 fallback event.
Key Takeaways
- On a fraud-scoring team (~450 RPS peak, ml
- g5.2xlarge), inference components plus April 2026 capacity-aware instance pools cut endpoint provisioning failures from 6 retries to 0, and p99 held at 68 ms through a g5→g6 fallback event
- AWS lifecycle notice (June 30, 2026): SageMaker Model Monitor is in maintenance for new customers after July 30, 2026
- Existing baselines remain valid; net-new pipelines should plan CloudWatch metrics and custom drift detection
- On April 21, 2026, Amazon SageMaker AI shipped capacity-aware inference with automatic instance fallback
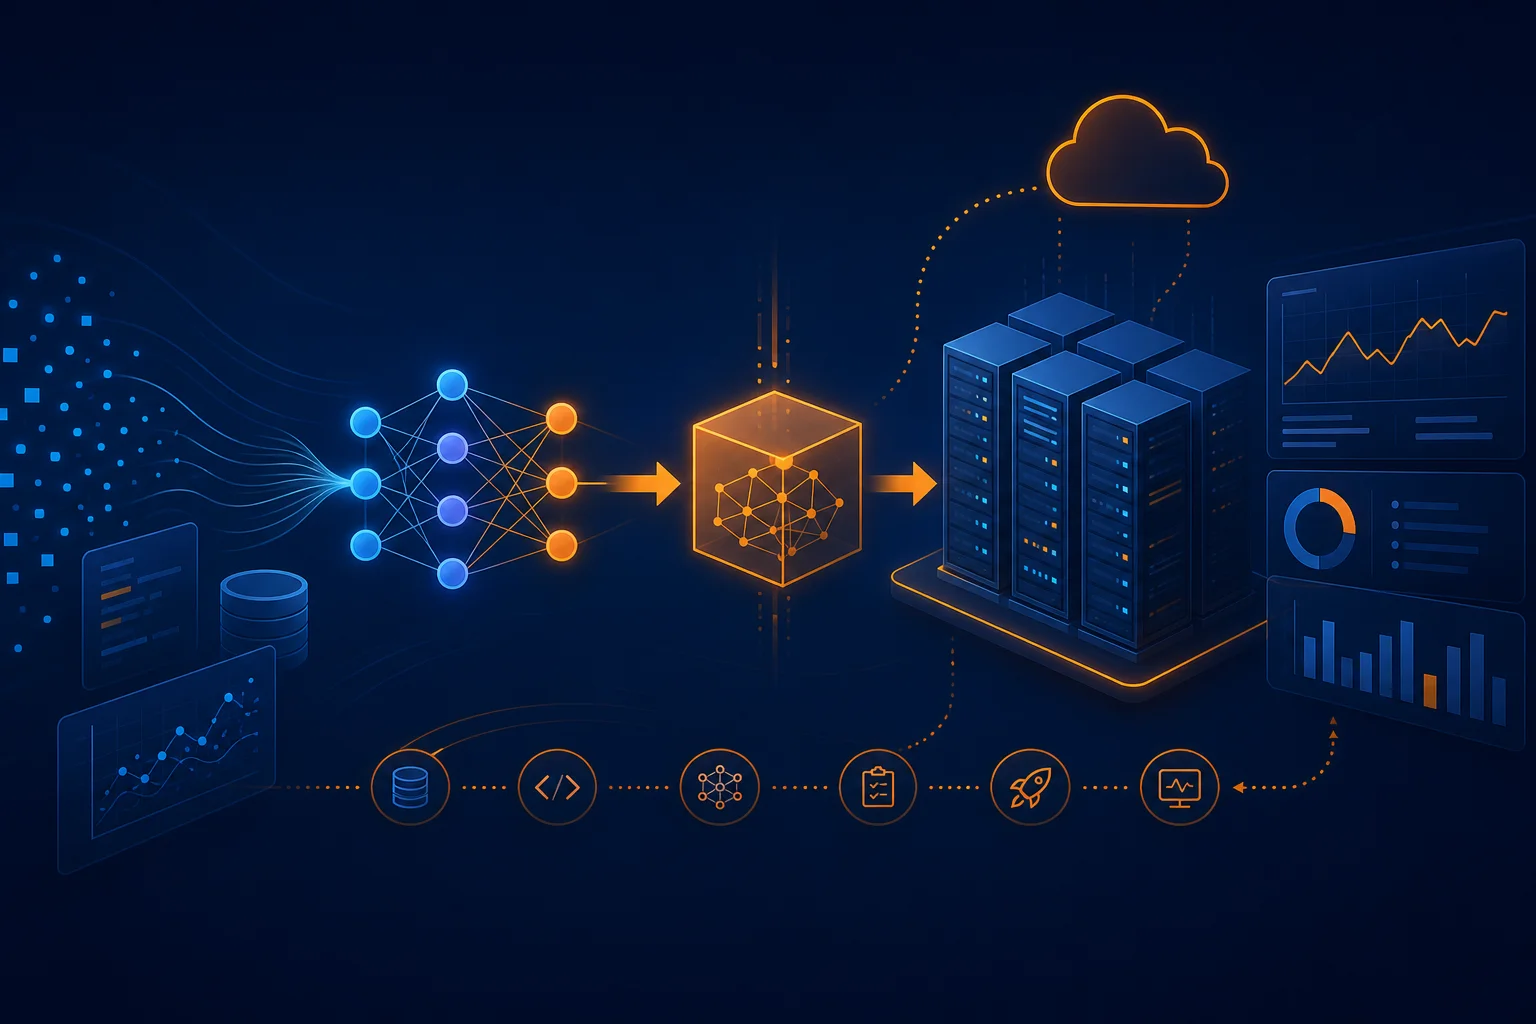
Table of Contents
On April 21, 2026, Amazon SageMaker AI shipped capacity-aware inference with automatic instance fallback. Prioritized instance pools provision the next hardware type when your first choice lacks capacity. That change matters because GPU endpoint creation failures were the top production blocker for teams who pinned a single ml.g5.* type in CI.
This post is the production deployment playbook: inference components, registry gates, monitors, and promotion. It is not Unified Studio migration, not training cost optimization, not Bedrock vs OpenAI, and not blue/green for generic apps (though variant weights reuse the same ideas).
Artifacts: deployment stage checklist, cost/latency worksheet CSV.
Production ladder: run in order
| Stage | Gate | Rollback trigger |
|---|---|---|
| 0 | Model Registry package + lineage | No registry → stop |
| 1 | Staging endpoint + load test 1.5× peak | p99 > SLA at 1× |
| 2 | Model Monitor baselines | Drift on shadow traffic |
| 3 | Registry approval + canary weights | 5xx > 0.1% |
| 4 | Cost tags + autoscale bounds | Idle GPU > 40% without scale-in |
Full checklist: deployment-stage-checklist.md.
Opinionated take: Inference components for all new real-time endpoints. Single-model endpoints are a dev convenience. Production needs independent scale and multi-model headroom without reprovisioning the entire endpoint.
Stage 1: Deploy with inference components
AWS CLI v2 + boto3 ≥ 1.34; region us-east-1 in examples below.
# Context: SageMaker AI real-time endpoint with inference component (July 2026 API)
aws sagemaker create-model --model-name fraud-xgb-v3 --primary-container Image=ACCOUNT.dkr.ecr.us-east-1.amazonaws.com/fraud:xgb-v3.2

aws sagemaker create-endpoint-config --endpoint-config-name fraud-prod-ic-cfg \
  --production-variants VariantName=AllTraffic,InitialInstanceCount=2,InstanceType=ml.g5.2xlarge

aws sagemaker create-endpoint --endpoint-name fraud-prod --endpoint-config-name fraud-prod-ic-cfg

aws sagemaker create-inference-component \
  --inference-component-name fraud-xgb-ic \
  --endpoint-name fraud-prod \
  --variant-name AllTraffic \
  --specification '{"ModelName":"fraud-xgb-v3","ComputeResourceRequirements":{"MinMemoryRequiredInMb":4096,"NumberOfAcceleratorDevicesRequired":1}}' \
  --runtime-config '{"CopyCount":2}'
For capacity-aware pools, set heterogeneous instance preferences in endpoint config (see AWS capacity-aware inference blog, April 2026). SageMaker tries your priority list at create, scale-out, and scale-in.
Stage 2: Model Monitor before traffic
# Context: boto3 1.34+, SageMaker SDK 2.x, staging endpoint already serving shadow traffic
from sagemaker.model_monitor import DefaultModelMonitor

monitor = DefaultModelMonitor(
    role="arn:aws:iam::ACCOUNT:role/SageMakerModelMonitor",
    instance_count=1,
    instance_type="ml.m5.xlarge",
    volume_size_in_gb=20,
    max_runtime_in_seconds=3600,
)

monitor.suggest_baseline(
    job_name="fraud-baseline-20260702",
    endpoint_input="fraud-staging",
    inference_attribute="predicted_label",
    record_preprocessor_source_uri="s3://ml-monitoring/preprocessor.py",
)
Schedule hourly monitors for fraud; daily for slow-drifting recommenders. Pair with CloudWatch alarms on Invocation5XXErrors and ModelLatency.
Stage 3: Promotion with registry + canary
- Set model package status to
Approvedin Model Registry (manual or pipeline gate). - Deploy new inference component version to staging; run shadow 0% prod weight.
- Shift prod variant weight 10% → 50% → 100% or swap endpoint config per blue/green guide.
- Keep previous model version ARN in runbook for < 5 min rollback.
Integrate with SageMaker Pipelines (training → evaluate → register → deploy steps), aligned with DevOps maturity model Level 3+ expectations.
Stage 4: Cost and capacity
| Lever | When |
|---|---|
| Instance pool fallback | GPU capacity errors in CI |
Auto-scaling on InvocationsPerInstance | Predictable diurnal fraud peaks |
| SageMaker AI Savings Plans | Steady GPU hours > $50k/mo; see Savings Plans guide |
| Async / batch transform | Scoring latency > 60s acceptable |
Model scenarios in cost-latency-worksheet.csv. The scale-to-zero row shows p99 2400 ms cold start, so it was rejected for real-time fraud.
When NOT to use SageMaker endpoints
| Situation | Alternative |
|---|---|
| Prompt-only LLM, no custom weights | Bedrock Converse API |
| Sub-10 ms at millions RPS | Neuron / Inferentia compiled models or edge |
| Batch nightly scores only | Batch Transform, no 24/7 endpoint |
| Team has no container ops | SageMaker JumpStart managed model; still an endpoint, but faster bootstrap |
What to do this week
- Register current prod model in Model Registry with lineage.
- Add instance pool to staging endpoint config; rerun failed CI provisions.
- Run 1.5× load test; export p99 to worksheet CSV.
- Create Model Monitor baseline from staging; alarm on drift + 5xx.
- Document rollback ARN and variant weight steps before next promotion.
What this post doesn’t cover
- Feature Store setup and offline/online sync: separate data engineering guide.
- Multi-model generative serving (LLM + reranker): Bedrock + AgentCore patterns.
- SageMaker HyperPod large-scale training: training cluster ops, not inference.
- Full MLOps platform selection (Databricks, Vertex): AWS-native path only.
Related: SageMaker consulting · DevOps pipeline setup · Application modernization
Frequently asked questions
When should we use inference components vs single-model endpoints?
When should we NOT use scale-to-zero on inference endpoints?
What breaks during GPU capacity shortages?
How does this differ from SageMaker Unified Studio migration?
When should we use Bedrock instead of SageMaker endpoints?
What could go wrong after enabling Model Monitor?
AWS Cloud Architect & AI Expert
AWS-certified cloud architect and AI expert with deep expertise in cloud migrations, cost optimization, and generative AI on AWS.