Amazon Redshift Data Warehouse Modernization Playbook (2026): Zero-ETL, Serverless, and Spectrum
Quick summary: For a retailer DW exit (~42 TB logical, 18 nightly Glue jobs), Aurora→Redshift zero-ETL retired 11 jobs and cut dashboard freshness from 6h to ~15 min. Concurrency scaling on zero-ETL (March 2026) absorbed Monday open spikes.
Key Takeaways
- For a retailer DW exit (~42 TB logical, 18 nightly Glue jobs), Aurora→Redshift zero-ETL retired 11 jobs and cut dashboard freshness from 6h to ~15 min
- Concurrency scaling on zero-ETL (March 2026) absorbed Monday open spikes
- In March 2026, Redshift announced concurrency scaling support for auto-copy and zero-ETL, so ingest peaks can add compute instead of stalling dashboards (What's New)
- It does not cover Serverless vs provisioned tier choice or the S3 Tables / Iceberg lake reference architecture, and it is not a Glue-only ETL tutorial
- Benchmark silhouette (not a cited client): Retail analytics, legacy DW ~42 TB logical, 18 nightly Glue jobs, dashboard freshness ~6 hours
Table of Contents
Zero-ETL integrations make operational data available in Amazon Redshift without you maintaining a classic ETL fleet for supported sources, including Aurora MySQL/PostgreSQL, RDS MySQL/PostgreSQL/Oracle, DynamoDB, and listed SaaS/apps (Redshift zero-ETL). In March 2026, Redshift announced concurrency scaling support for auto-copy and zero-ETL, so ingest peaks can add compute instead of stalling dashboards (What’s New).
This is the warehouse modernization playbook. It does not cover Serverless vs provisioned tier choice or the S3 Tables / Iceberg lake reference architecture, and it is not a Glue-only ETL tutorial.
Artifacts: path matrix, TCO worksheet, architecture diagram (draw.io).
Modernization sequence
- Assess: freshness SLOs, license cost, job inventory
- Land: zero-ETL for supported sources; Glue only for true transforms
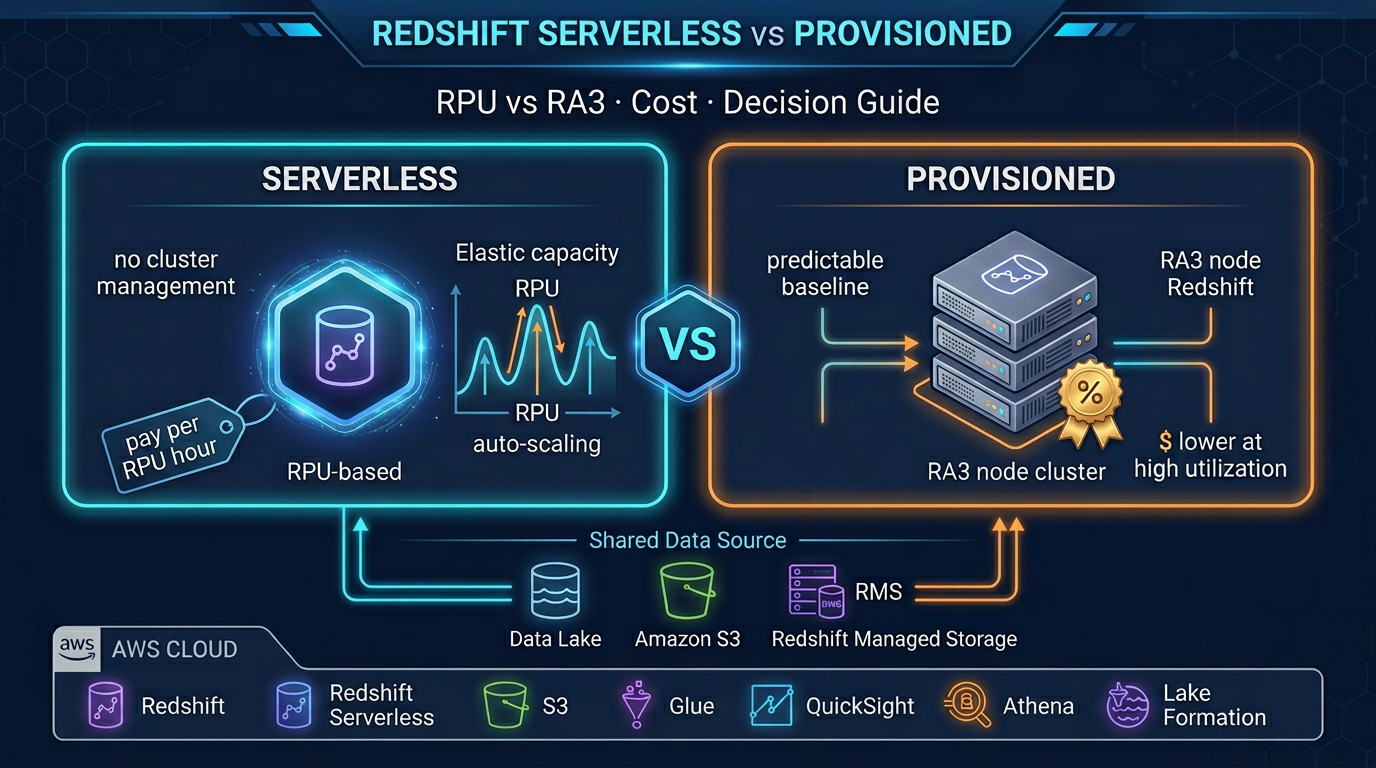
- Size: Serverless default; RA3 if flat-high baseline (tier post)
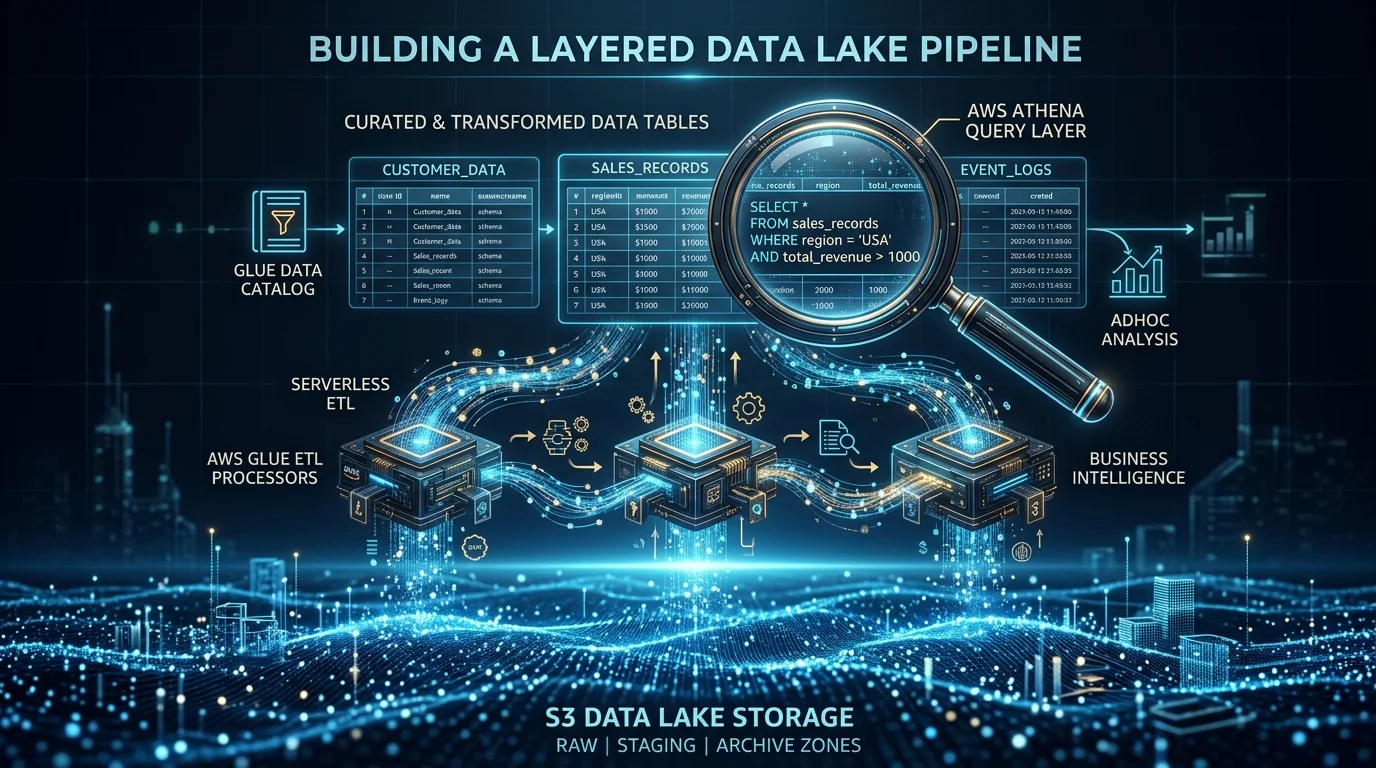
- Park cold: S3 / Iceberg + Spectrum; lake detail in modern data lake post
- Cut over: BI first, then delete duplicate jobs
Opinionated take: Delete Glue jobs only after consumers read the zero-ETL schema for two billing cycles. Early deletion is how you recreate the pipeline under an incident bridge.
Reference flow
Aurora / RDS / DynamoDB ──► Zero-ETL ──► Redshift (Serverless or RA3)
On-prem / complex transforms ──► Glue ──► Redshift + S3
S3 cold / Iceberg ──► Spectrum / lake query ──► same BI tools
Target prerequisites include case sensitivity and IAM/resource policy setup (configure Redshift target).
Path matrix
Use modernization-path-matrix.md to choose Serverless vs RA3 vs zero-ETL vs Spectrum-heavy designs.
What broke: case sensitivity
What to do this week
- List every nightly job and tag replicate vs transform.
- Enable zero-ETL on one Aurora or RDS source into a Serverless workgroup.
- Turn on case sensitivity and confirm concurrency scaling eligibility in your Region.
- Fill the TCO worksheet with your license line items.
What this post doesn’t cover
- Detailed Serverless RPU tuning (see tier-choice post)
- Full lakehouse governance (SageMaker Catalog operating model)
- Streaming-first architectures (Kinesis/MSK)
- Oracle Exadata-specific exit tooling beyond DMA/partner programs
Frequently asked questions
When should we NOT use zero-ETL?
Serverless or provisioned for the modern warehouse?
What could go wrong with zero-ETL cutover?
Where does Spectrum fit?
How is this different from the modern data lake S3 Tables post?
Did concurrency scaling change zero-ETL behavior in 2026?
AWS Cloud Architect & AI Expert
AWS-certified cloud architect and AI expert with deep expertise in cloud migrations, cost optimization, and generative AI on AWS.