Connect Evaluation Checks (Oct 2026): Warnings Don't Stop Activation
Quick summary: On October 9, 2026 Amazon Connect Customer added Save and validate in 8 Regions. Structural errors block activation. Gen AI warnings do not. The Gen AI check is capped at 3 in parallel and 30 per hour.
Key Takeaways
- On October 9, 2026 Amazon Connect Customer added Save and validate in 8 Regions
- The Gen AI check is capped at 3 in parallel and 30 per hour
- On October 9, 2026, AWS added automated checks that suggest edits to Amazon Connect Customer performance evaluation forms
- The generative AI stage allows 3 validations in parallel and 30 per hour on each instance
- The check is in 8 Regions
Table of Contents
On October 9, 2026, AWS added automated checks that suggest edits to Amazon Connect Customer performance evaluation forms. In the admin website, Save and validate runs two stages. Structural problems return as Errors and block activation. If the form has generative AI questions and no structural errors, those questions are checked against 11 best practices and return as Warnings. Warnings do not block activation. The generative AI stage allows 3 validations in parallel and 30 per hour on each instance. The check is in 8 Regions.
AWS’s own example is the question “Did the agent provide a sales disclosure?” The check asks the manager to name the exact disclosure. Activate with that warning still open, and the model can mark the question Yes because the transcript contains the word “disclosure.”
Cases CSV export, shipped August 4, 2026 in 10 Regions, is a different control. See Connect Cases CSV export. Broader design (flows, workspace, Cases) stays on Amazon Connect consulting.
What shipped on October 9, 2026
| Piece | What AWS documents |
|---|---|
| Entry | Evaluation form → Save → Save and validate |
| Stage 1 | Structural and configuration rules. Findings are Errors. They block activation. |
| Stage 2 | Runs only when stage 1 is clean and the form has Gen AI questions. Findings are Warnings. |
| Rate limit | 3 Gen AI validations in parallel, 30 per hour, per instance. Structural checks are outside that cap. |
| Resolved | Hides a finding in the side panel. Does not re-run validation and does not change activation state. |
| Regions | 8, listed in the FAQ. Seoul and Cape Town are absent. |
| Permission | Analytics and Optimization → Evaluation forms → manage form definitions → Create |
A green banner means the pass found no recommendations. Findings reopen from the Findings control beside a question, or from Save and validate again.
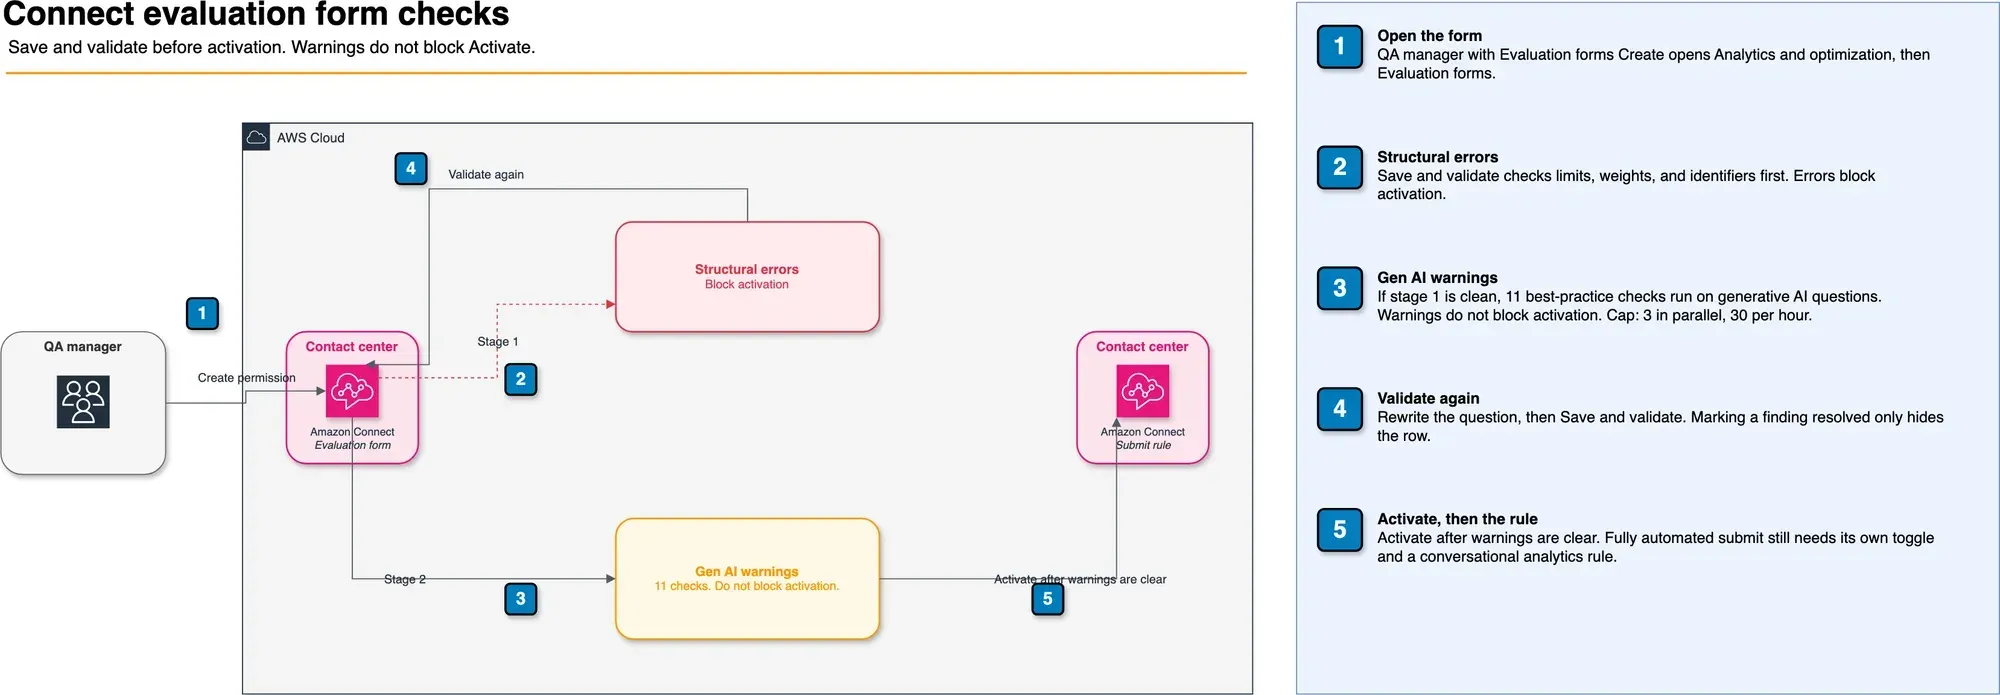
Figure: Save and validate, then Activate. Open the draw.io.
The 11 checks on a Gen AI question
AWS lists these for every question automated with generative AI. Warnings from this list do not block activation. Treat them as the quality bar anyway.
| Check | What fails it |
|---|---|
| Question phrasing | Title is a heading or a statement, not a full question ending in a question mark |
| Instructions present | No instructions telling the model how to answer |
| Answer option language | Acronyms or abbreviations in the options |
| Answer option conciseness | Options carry commentary or conditions instead of a short label |
| Transcript answerability | The answer needs data outside the transcript and the instructions |
| Positive action framing | The question asks the model to detect that something did not happen |
| Plain language | Instructions use abbreviations, acronyms, or in-house jargon |
| Spelling | Misspellings in the title, instructions, or options |
| External systems | Instructions mention a screen or state the transcript cannot show |
| Non-textual cues | Volume, pitch, speaking speed, or vocal tone. Professionalism and empathy are allowed |
| PII values | A specific personal-data value appears in the question or instructions. Scoring whether the agent handled PII correctly is allowed |
Clear warnings before Activate
Clear every Warning, then Activate. AWS still lets you activate with Warnings open. Another validation pass shares the 3-parallel and 30-per-hour cap, so a bulk cleanup of many forms can stall. Shipping the vague question costs a score you cannot explain to a supervisor.
Split the work the way the admin guide already splits automation:
- Metrics for numbers the contact already stores: longest hold, hold count, interaction duration, interruptions, sentiment score.
- Contact categories when the phrase is a rule. The greeting example in the docs is “Thank you for calling” in the first 30 seconds, labeled
ProperGreeting. - Generative AI for single-select and text questions a person could answer from the transcript plus the instructions. On fully automated submit, that path is capped at 10 questions per contact. The cap is the existing conversational-analytics quota, not a limit introduced on October 9.
How answers get filled at runtime
Authoring checks and runtime scoring are different steps. Save and validate judges the form. After activation, conversational analytics fills answers on each contact.
| Automation | Question types | Use it when |
|---|---|---|
| Contact categories | Single select, multiple select | The expected words or call reason already exist as a rule |
| Generative AI | Single select, text | The transcript and your instructions are enough to decide |
| Metrics | Number | The fact is hold time, interruptions, sentiment, or a similar contact metric |
Fully automated submission is a separate toggle, Enable fully automated submission of evaluations, plus a conversational-analytics rule that chooses which contacts to score. Evaluators can still edit and resubmit. Self-service contacts (a Lex bot or an AI agent) use the contact interaction type under Additional settings. They are a different target from the human-agent form, with the same authoring check once a question is on generative AI.
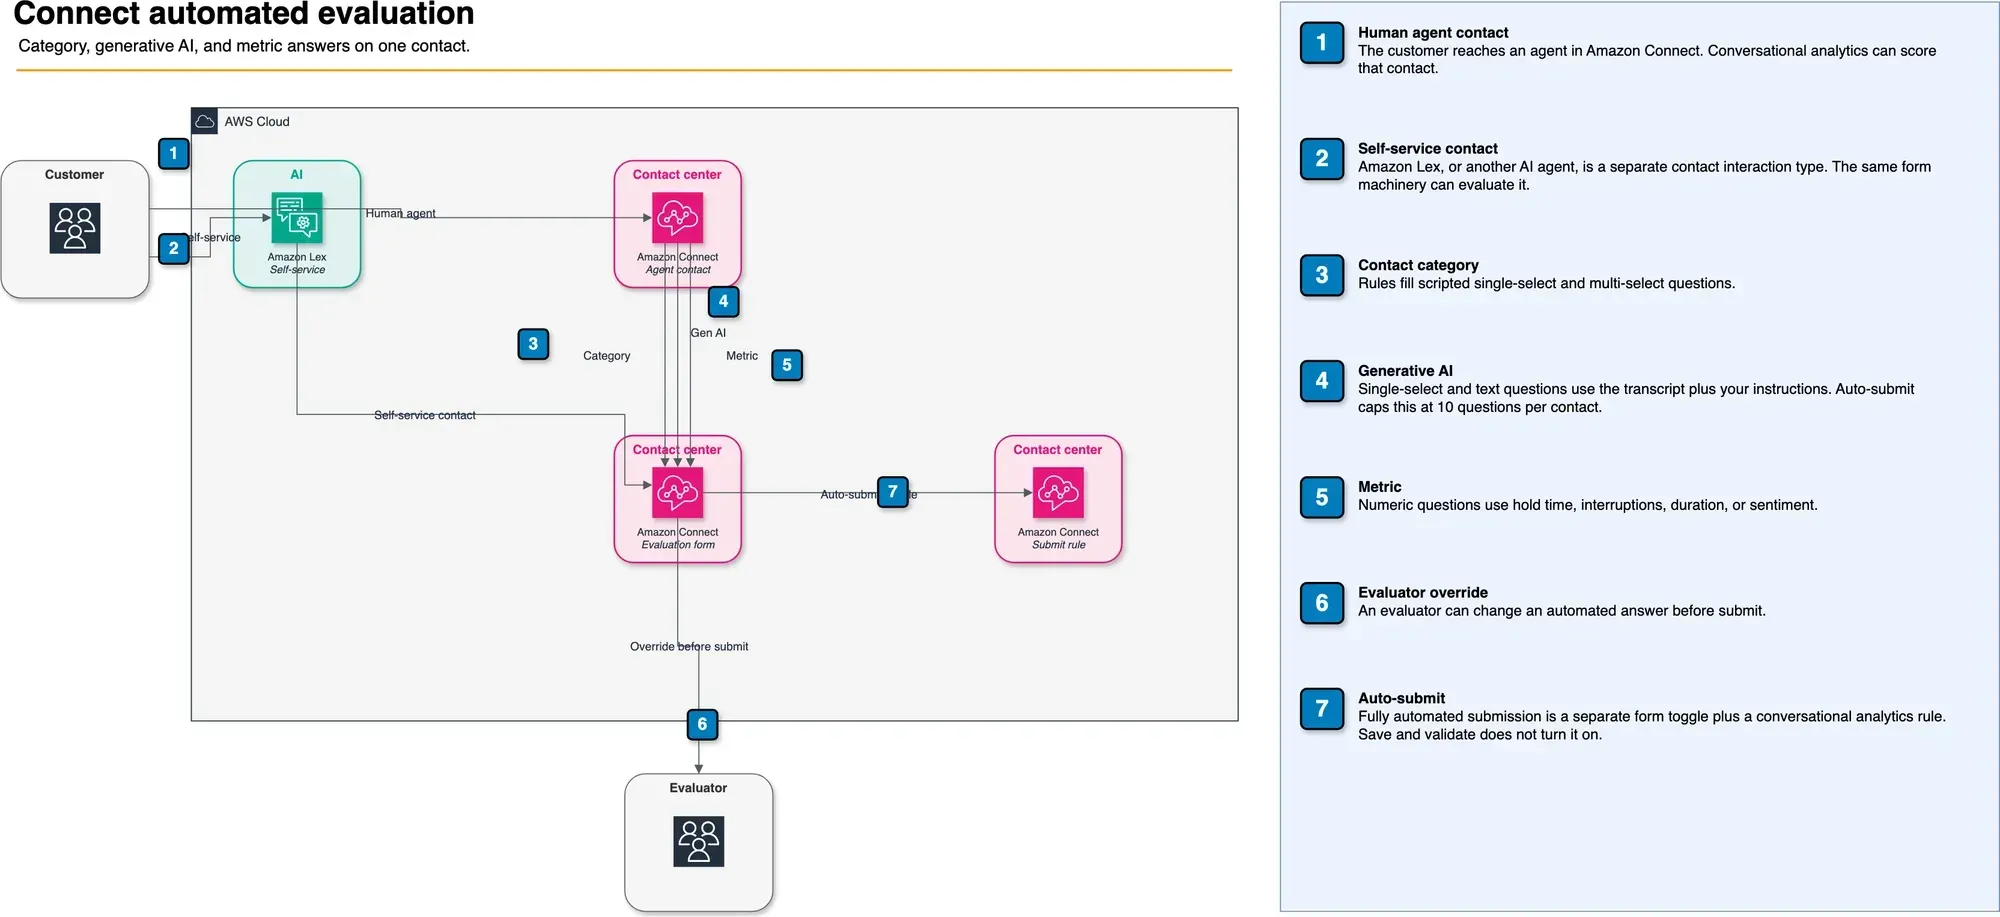
Figure: Three ways a contact gets an answer, plus override and auto-submit. Open the draw.io.
Update, October 26, 2026: outcome metrics, segments, and flow tests
Three Connect Customer launches on October 26 sit next to the evaluation form. The form scores what the agent did. These score what happened to the customer, and whether the flow in front of the agent returned what you expected.
| Launch | What AWS documents | Regions |
|---|---|---|
| Outcome metrics | Scores each interaction for four outcomes: customer left satisfied, customer at risk of churn, customer made a purchase, need resolved in self-service. Each has a default definition you can change. Exposed in analytics dashboards and APIs. | All Connect Customer Regions |
| Segments | Breaks metrics down by customer lifetime value (LTV) and repeat-caller status, so you can compare repeat callers with everyone else or look only at your highest-LTV customers. | Regions with Connect Customer Profiles |
| Flow action validation | Testing and simulation now checks the data an action returns, not only that it started: a Lambda response, a resolved Amazon Lex intent, or variables set by an Agentic CX block. A failed test points at the action that returned the wrong value. | Per the Region availability page |
None of the three announcements lists a price.
Read the form score next to the outcome score before you change coaching. An agent can pass every question on the form while the contact is scored at churn risk. That gap is the conversation a supervisor should have. Change the default outcome definitions only after you have written down what “resolved” and “at risk” mean for your queues, or the dashboard will measure something nobody agreed to.
Segments need Customer Profiles. The LTV split depends on it. If your instance has no profiles, the repeat-caller view is the one to plan around.
Test the self-service flow before you score it. A Lex bot or AI agent contact goes through its own evaluation form (see the runtime section above). If the flow routes on the wrong intent, the evaluation grades the wrong conversation. Add a test that asserts the resolved intent and the Lambda response, then score. Since October 30, 2026 you can run that test against a new flow version before the production alias points at it.
We have not run these metrics on a live queue. This section describes the announcements and the admin guide’s metrics reference, not a measured result.
What to do this week
- Confirm the instance Region is one of the 8. Seoul and Cape Town can have Cases and still lack this check.
- Open one live generative AI form and choose Save and validate. You need the Evaluation forms Create permission.
- Rewrite warnings that fail transcript answerability, positive action framing, or external-system references. Put the exact sentence in the instructions.
- Validate again. Do not treat Resolved as a second pass. If the side panel says you hit 3 in parallel or 30 in the hour, wait and retry. Structural validation still runs.
- Leave fully automated submit off until a supervisor has compared auto-scores to recordings on the questions you rewrote.
- Write down what “satisfied,” “at risk,” “purchase,” and “self-service resolved” mean for each queue before you edit the October 26 outcome-metric defaults.
Need the form model, the security profiles, and the rule design done as one pass? FactualMinds is an AWS Select Tier Services Partner. Start at Amazon Connect consulting or contact us.
What this post doesn’t cover
- Connect Customer pricing for voice, chat, conversational analytics, or evaluations. Use the current pricing page for your Region.
- A calibration study. We have not scored a queue before and after these checks.
- Scoring design. Percentage versus points, automatic fail, weights, and performance thresholds are in Steps 5 and 8 of the same admin guide.
- PDF import of a form from another quality tool (documented max 2 MB). Useful, and out of scope here.
- The validation API. Console path above is the one this post verified against the October 9 what’s new and Step 9 of the admin guide.
Related reading
- Amazon Connect Consulting
- Connect Cases CSV Export (Aug 2026)
- HIPAA-Compliant Architecture on AWS
- AWS for Retail: Complete Guide
Frequently asked questions
What did AWS ship for Connect evaluation forms on October 9, 2026?
When should we not rely on this check?
What could go wrong if we activate with warnings still open?
Which Regions include the October 9 check?
How many questions can generative AI answer on one contact?
What did Connect Customer add on October 26, 2026?
Do outcome metrics replace the evaluation form?
Should every contact be auto-submitted on day one?
AWS Cloud Architect & AI Expert
AWS-certified cloud architect and AI expert with deep expertise in cloud migrations, cost optimization, and generative AI on AWS.
 Nash Ogden